Blog Categories and Tags: Structure That Doesn’t Create Index Bloat
How to structure blog categories and tags for SEO without generating index bloat. A practical checklist and a 4-8 category rule.
Use 4 to 8 stable parent categories that map to your core business topics, and treat tags as an optional, tightly controlled layer rather than a free-for-all. The most common SEO mistake with blog taxonomy isn’t choosing the wrong categories, it’s letting tag pages multiply unchecked until a site with 100 blog posts has 400+ indexed archive pages competing with each other for the same keywords. Categories should be built to last years; tags should be added sparingly, and most tag archive pages should be noindexed by default.
Published August 2026.
What’s the actual difference between categories and tags?
Categories are the primary, hierarchical way you organise content: think of them as the chapters of a book. A digital marketing blog might use categories like SEO, Content Marketing, Paid Ads, and Web Development. Every post should sit in exactly one, or at most two, categories, because categories define the site’s core information architecture and show up in the main navigation and breadcrumbs.
Tags are a flatter, cross-cutting label system, closer to an index at the back of a book than a table of contents. A single post about local SEO for restaurants might carry tags like “local SEO,” “restaurants,” and “Google Business Profile,” cutting across whatever category it’s filed under. Tags are useful for readers browsing a narrow topic, but they generate a page for every tag used, and that’s where the SEO risk starts.
How does index bloat actually happen from categories and tags?
Every category and every tag in WordPress and most CMS platforms automatically generates an archive page, and by default, that archive page is indexable. If a team applies five or six tags to every post without a plan, a 100-post blog can generate hundreds of tag archive pages, most of which contain only two or three posts and thin, often auto-generated, description text. Search Engine Land’s guide to index bloat describes exactly this pattern: a site’s indexed page count balloons well past its actual content count because tag pages, date archives, and author archives get indexed by default, and those thin pages compete with a site’s substantive content for the same crawl budget and, sometimes, the same keywords.
The fix isn’t eliminating tags. It’s being deliberate about which tag pages are allowed to be indexed, and keeping the rest set to noindex so they still help on-site navigation without cluttering search results.
How many categories should a blog actually have?
| Category count | What it usually signals |
|---|---|
| 1-3 categories | Too few for most blogs; forces unrelated topics together and weakens topical clarity |
| 4-8 categories | The workable range for most business blogs; matches core service or topic pillars |
| 10+ categories | Usually a sign categories are being used like tags, fragmenting topical authority |
A category structure with 4 to 8 stable, business-aligned categories tends to hold up over years of publishing without needing a rework. Categories that map to genuine content pillars, the topics you’ll keep publishing about indefinitely, age far better than categories created for a single content push and then abandoned.
A practical checklist for setting up taxonomy
- Pick categories from your content pillars, not your org chart. Categories should reflect what readers search for, not internal department names.
- Assign one primary category per post. A secondary category is sometimes fine; three or more usually means the post needs a narrower topic or the category list needs consolidating.
- Treat tags as optional, not mandatory. Only add a tag if it will realistically apply to three or more future posts.
- Noindex thin tag and category archives. Any archive page with fewer than roughly three to five posts and no unique intro copy is a candidate for noindex.
- Audit taxonomy every 6-12 months. Merge categories that overlap, and prune tags that were used once and never again.
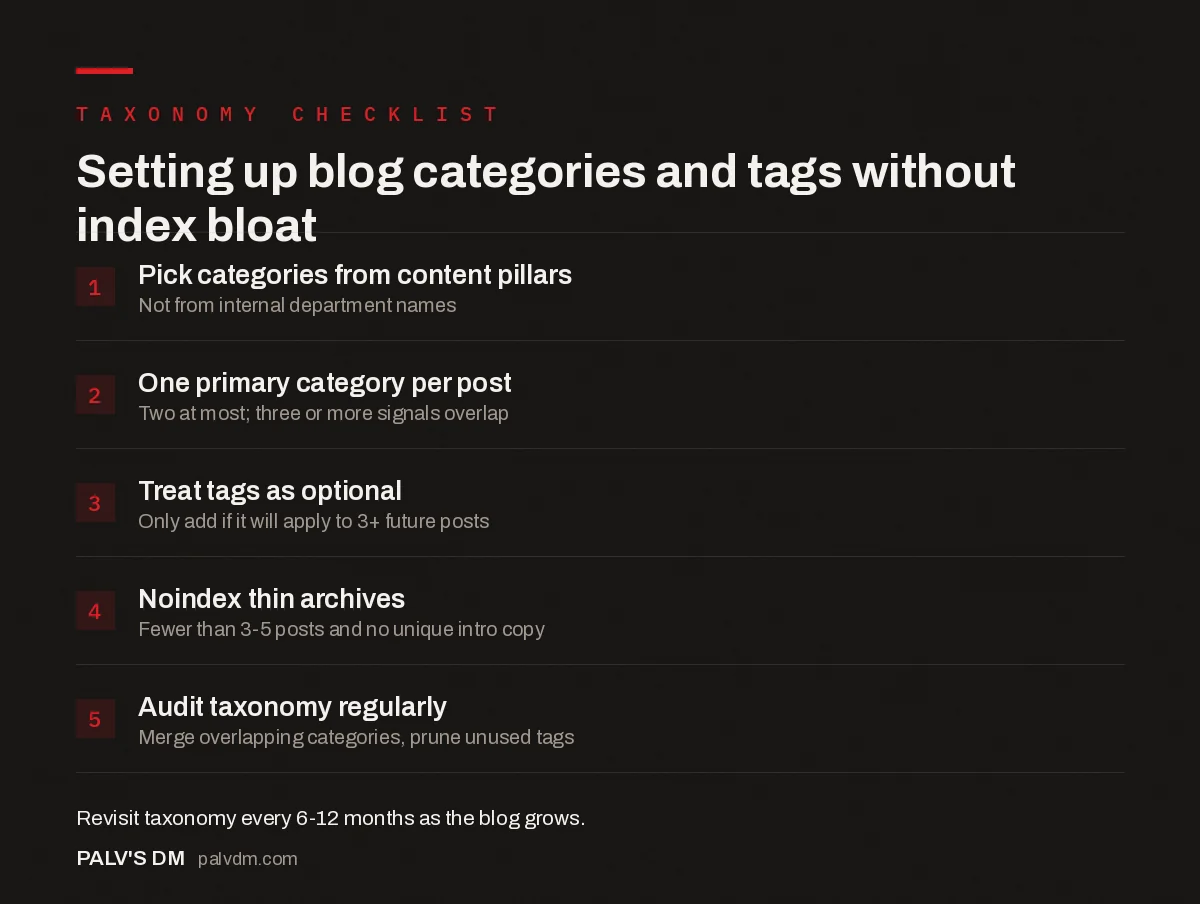
Setting up blog categories and tags without index bloat
- Pick categories from content pillars. Not from internal department names.
- One primary category per post. Two at most; three or more signals overlap.
- Treat tags as optional. Only add if it will apply to 3+ future posts.
- Noindex thin archives. Fewer than 3-5 posts and no unique intro copy.
- Audit taxonomy regularly. Merge overlapping categories, prune unused tags.
What mistakes show up most often in real taxonomy audits?
Five patterns account for most of the index bloat problems found when auditing an established blog’s category and tag structure.
- Tags created per post instead of per concept. A writer under deadline pressure invents a new tag rather than checking whether an existing one already covers the topic, producing near-duplicate tags like “email marketing,” “email marketing tips,” and “email campaigns” that each carry too few posts to rank.
- Categories that mirror an old org chart. A site restructures its internal teams and someone updates the blog categories to match, producing labels like “Team Updates” or “Product Marketing” that describe who wrote the post rather than what a reader searched for.
- No default noindex rule for new tags. Most WordPress SEO plugins let you set tag archives to noindex by default, and most sites never touch that setting, so every new tag is indexable from the first post that uses it.
- Category pages left as bare post lists. A category with real search demand still underperforms if the archive page has no intro copy, since a bare list of titles gives search engines little to work with.
- Migrating platforms without re-auditing taxonomy. A CMS migration often imports the old category and tag structure wholesale, carrying forward years of bloat instead of using the move as a point to consolidate.
A worked example: cleaning up a bloated taxonomy
Take a hypothetical but realistic case: a marketing blog with 180 published posts, 11 categories, and 340 tags, most of the tags used on only one or two posts. The category list mixes genuine topic pillars (“SEO,” “Content Marketing”) with leftover department names (“Team News,” “Case Studies,” used more like a tag than a category). Fixing this in a single pass looks like:
- Consolidate categories to the pillars that will keep publishing. “Team News” and one-off announcement posts move into a general “Company” category set to noindex, since it isn’t a topic readers search for. “Case Studies” becomes a tag applied within relevant topic categories rather than a standalone category, since case studies aren’t a distinct subject, they’re a content format that cuts across subjects.
- Merge near-duplicate tags. “email marketing,” “email campaigns,” and “email tips” collapse into a single “email marketing” tag, with the old tag archive URLs 301-redirected to the surviving one so any accumulated links or bookmarks still resolve.
- Noindex everything under five posts. Of the 340 original tags, fewer than 30 have five or more posts attached. The rest get set to noindex, which removes roughly 300 thin, low-value URLs from the index without deleting a single tag or post.
- Write short intro copy for the surviving category and tag pages. Two to three sentences per archive page, explaining what the category covers and linking to the two or three strongest posts in it, gives search engines more to work with than a bare list.
The result of this kind of cleanup is rarely a traffic spike on its own. It’s a reduction in the number of thin pages competing for crawl attention, which tends to show up gradually as better crawl efficiency and, over months, as clearer rankings for the category pages.
Should category and tag pages be indexed at all?
Strong category pages, the ones aligned with real search demand and populated with a healthy number of posts, are worth indexing and often worth treating like pillar pages themselves, with a short intro paragraph explaining the topic and a curated list of posts underneath. Weak tag pages, especially ones with only one or two posts and no unique content beyond a list of titles, are better left noindexed. They still function for on-site navigation; a noindex tag doesn’t remove the tag or hide it from visitors, it only tells search engines not to include that specific archive URL in results.
The decision isn’t binary at the site level. It’s a per-page-type decision: index categories that carry real topical weight, noindex thin tag archives, and revisit the split as the blog grows and some tags accumulate enough posts to become genuinely useful landing pages in their own right.
How does this connect to pillar pages and content clusters?
A well-built category structure and a pillar page strategy solve overlapping but distinct problems. Categories are a taxonomy decision built into the CMS; pillar pages are editorial hub pages you write and maintain by hand, linking out to every post in a cluster. A category archive page lists posts automatically and offers little editorial context. A pillar page is a standalone piece of content that explains the topic and links to the cluster with intent, which tends to perform better for competitive head terms. Many sites use both: a category to keep the CMS organised, and a hand-built pillar page for the category’s most important topic, cross-linked with the category archive.
Frequently asked questions
Can a blog post have more than one category?
Technically yes in most CMS platforms, but assigning a post to more than two categories usually signals the categories overlap too much or the post is trying to cover too many topics at once. One primary category per post keeps the taxonomy cleaner and avoids diluting which category “owns” that post in search engines’ eyes.
Do tag pages hurt SEO even if they’re never linked internally?
They can still get discovered and indexed through XML sitemaps or crawlers finding them via the URL structure, even without internal links pointing to them. If a tag page is auto-generated and thin, it’s worth explicitly noindexing it rather than assuming the lack of internal links keeps it out of the index.
How many posts should a category have before it’s worth indexing?
There’s no fixed number, but a common practical threshold is somewhere around five or more posts with genuine topical relevance to each other. Below that, the archive page often reads as thin and may be better left noindexed until the category has grown.
Should categories change as a blog grows?
Yes, periodically. A category structure set up for 20 posts often doesn’t fit at 200. Reviewing and consolidating categories every 6 to 12 months, merging ones that have become redundant and splitting ones that have grown too broad, keeps the taxonomy matched to the actual content.
Getting the structure right from the start
Blog taxonomy is easy to set up carelessly and expensive to fix later, because reorganising categories after hundreds of posts means redirects, link updates, and potential ranking disruption. Starting with 4 to 8 durable categories, treating tags as optional rather than automatic, and noindexing thin archive pages keeps a growing blog from quietly generating hundreds of low-value indexed pages. If you’re planning or restructuring a blog’s taxonomy alongside a broader content build-out, our content writing service includes information architecture as part of the initial content strategy, not an afterthought.
This post is part of our pillar pages and cluster content guide, and connects to our broader content strategy guide. If you’re deciding what to do with older, weaker posts as part of the same clean-up, see our content audit framework for scoring pages as keep, improve, merge, or kill.